Weekend Sale Special - 75% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: w75best

Databricks Databricks-Generative-AI-Engineer-Associate Dumps

Databricks Certified Generative AI Engineer Associate Questions and Answers

Question 1

A Generative AI Engineer is developing a chatbot designed to assist users with insurance-related queries. The chatbot is built on a large language model (LLM) and is conversational. However, to maintain the chatbot’s focus and to comply with company policy, it must not provide responses to questions about politics. Instead, when presented with political inquiries, the chatbot should respond with a standard message:

“Sorry, I cannot answer that. I am a chatbot that can only answer questions around insurance.”

Which framework type should be implemented to solve this?

Options:

A.

Safety Guardrail

B.

Security Guardrail

C.

Contextual Guardrail

D.

Compliance Guardrail

Question 2

What is the most suitable library for building a multi-step LLM-based workflow?

Options:

A.

Pandas

B.

TensorFlow

C.

PySpark

D.

LangChain

Question 3

A Generative AI Engineer is building a compound AI system for an organization. The goal is to automate the processing of incoming customer event reports against a coding system and corporate-guidelines documentation. The system must handle three distinct user-request types: answering questions from guidelines documents, extracting specific event codes from reviewers’ notes, and routing ambiguous requests to the appropriate specialized handler. All three capabilities must operate under a single entry point that interprets user intent and delegates accordingly.

Which Agent Brick should serve as the top-level orchestrator in this architecture?

Options:

A.

Multi-Agent Supervisor, because it can be used without Knowledge Assistant and Information Extraction agents.

B.

Knowledge Assistant, because the chatbot interface can handle multi-turn conversations.

C.

Knowledge Assistant, because it can be configured with multiple vector indexes to handle all three request types simultaneously.

D.

Multi-Agent Supervisor, because it interprets incoming requests and delegates tasks to specialized sub-agents.

Question 4

A Generative AI Engineer is building a multi-turn chat app with LangGraph on Databricks. The app must persist chat history—messages, roles, timestamps, and session IDs—for many concurrent users, support SQL queries, and stay governed in Unity Catalog. The engineer also wants ACID guarantees, low-latency reads and writes, and an easy way to sync chat data into Delta tables for analytics and model training.

Which approach fits these requirements?

Options:

A.

Store conversation history in MLflow runs and retrieve it via the MLflow Tracking API inside LangGraph nodes.

B.

Use Lakebase with a chat_history table wired to a Postgres-backed LangGraph checkpoint/memory component and enable synchronization from Lakebase into Delta tables.

C.

Write each turn from a custom LangGraph node directly into a Delta table with Spark append, then query history via Spark SQL on every request.

D.

Use a custom in-memory LangGraph state store running on the Databricks cluster driver, and periodically snapshot the state to JSON files in DBFS.

Question 5

A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here’s a sample email:
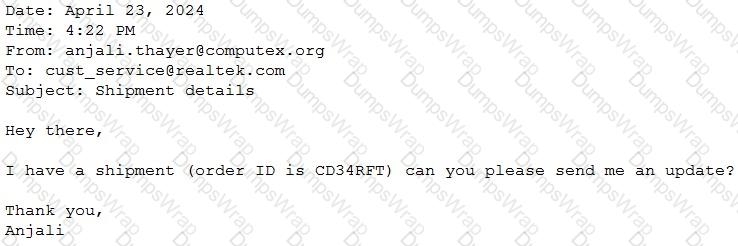
as

They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.

Which prompt will do that?

Options:

A.

You will receive customer emails and need to extract date, sender email, and order ID. You should return the date, sender email, and order ID information in JSON format.

B.

You will receive customer emails and need to extract date, sender email, and order ID. Return the extracted information in JSON format.

Here’s an example: {“date”: “April 16, 2024”, “sender_email”: “sarah.lee925@gmail.com”, “order_id”: “RE987D”}

C.

You will receive customer emails and need to extract date, sender email, and order ID. Return the extracted information in a human-readable format.

D.

You will receive customer emails and need to extract date, sender email, and order ID. Return the extracted information in JSON format.

Question 6

A Generative Al Engineer is building a RAG application that answers questions about internal documents for the company SnoPen AI.

The source documents may contain a significant amount of irrelevant content, such as advertisements, sports news, or entertainment news, or content about other companies.

Which approach is advisable when building a RAG application to achieve this goal of filtering irrelevant information?

Options:

A.

Keep all articles because the RAG application needs to understand non-company content to avoid answering questions about them.

B.

Include in the system prompt that any information it sees will be about SnoPenAI, even if no data filtering is performed.

C.

Include in the system prompt that the application is not supposed to answer any questions unrelated to SnoPen Al.

D.

Consolidate all SnoPen AI related documents into a single chunk in the vector database.

Question 7

A Generative AI Engineer is building an interactive catalog for a company’s inventory system that allows users to search for any item using a plain-text description. There are currently about 17,000 items, and new items are not frequently added. They need a solution that will be the most cost-effective and easy for the company to maintain.

Which solution should the engineer choose?

Options:

A.

Storage-optimized vector search with a Direct Vector Access index, triggered sync.

B.

Standard vector search with Databricks-managed embeddings and a Delta Sync index, continuous sync.

C.

Standard vector search with self-managed embeddings and a Delta Sync index, continuous sync.

D.

Standard vector search with Databricks-managed embeddings and a Delta Sync index, triggered sync.

Question 8

A Generative AI Engineer has been reviewing issues with their company ' s LLM-based question-answering assistant and has determined that a technique called prompt chaining could help alleviate some performance concerns. However, to suggest this to their team, they have to clearly explain how it works and how it can benefit their question-answering assistant. Which explanation do they communicate to the team?

Options:

A.

It allows you to break down complex tasks into multiple independent subtasks. This enables the assistant to generate more comprehensive and accurate responses.

B.

It allows you to reduce the latency of your applications. By having multiple chains participating in the response as a chain, you increase the rate at which the response is generated.

C.

It allows you to decrease the effort involved in crafting a prompt. Chains make it possible to reuse prompt text across multiple different use cases.

D.

It reduces the average cost of a typical request. Chains make more efficient use of the tokens produced to generate higher quality responses with fewer tokens.

Question 9

A Generative AI Engineer is building a Generative AI system that suggests the best matched employee team member to newly scoped projects. The team member is selected from a very large team. The match should be based upon project date availability and how well their employee profile matches the project scope. Both the employee profile and project scope are unstructured text.

How should the Generative Al Engineer architect their system?

Options:

A.

Create a tool for finding available team members given project dates. Embed all project scopes into a vector store, perform a retrieval using team member profiles to find the best team member.

B.

Create a tool for finding team member availability given project dates, and another tool that uses an LLM to extract keywords from project scopes. Iterate through available team members’ profiles and perform keyword matching to find the best available team member.

C.

Create a tool to find available team members given project dates. Create a second tool that can calculate a similarity score for a combination of team member profile and the project scope. Iterate through the team members and rank by best score to select a team member.

D.

Create a tool for finding available team members given project dates. Embed team profiles into a vector store and use the project scope and filtering to perform retrieval to find the available best matched team members.

Question 10

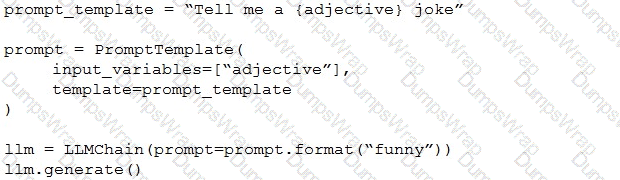
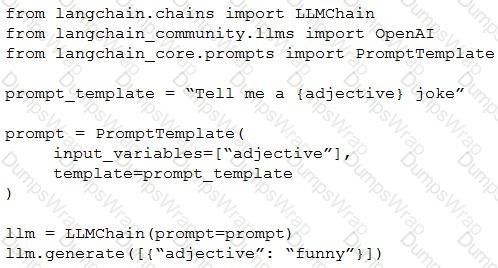
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.
as

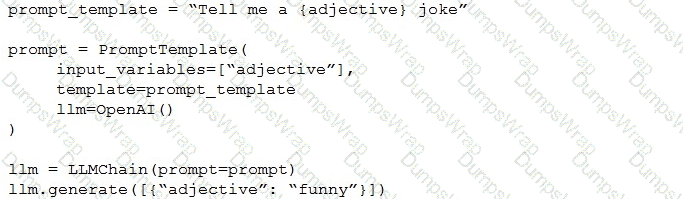
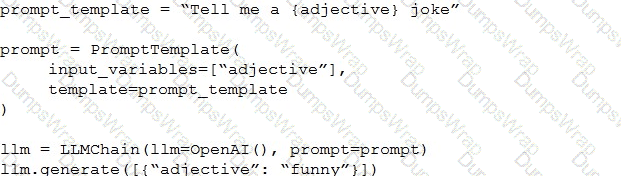
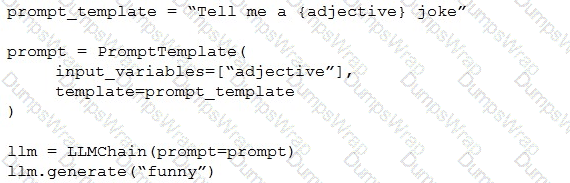
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?

A)
as

B)

as

C)

as

D)

as

Options:

A.

Option A

B.

Option B

C.

Option C

D.

Option D

Question 11

A Generative Al Engineer is developing a RAG system for their company to perform internal document Q & A for structured HR policies, but the answers returned are frequently incomplete and unstructured It seems that the retriever is not returning all relevant context The Generative Al Engineer has experimented with different embedding and response generating LLMs but that did not improve results.

Which TWO options could be used to improve the response quality?

Choose 2 answers

Options:

A.

Add the section header as a prefix to chunks

B.

Increase the document chunk size

C.

Split the document by sentence

D.

Use a larger embedding model

E.

Fine tune the response generation model

Question 12

After changing the response generating LLM in a RAG pipeline from GPT-4 to a model with a shorter context length that the company self-hosts, the Generative AI Engineer is getting the following error:

as

What TWO solutions should the Generative AI Engineer implement without changing the response generating model? (Choose two.)

Options:

A.

Use a smaller embedding model to generate

B.

Reduce the maximum output tokens of the new model

C.

Decrease the chunk size of embedded documents

D.

Reduce the number of records retrieved from the vector database

E.

Retrain the response generating model using ALiBi

Question 13

A Generative Al Engineer is tasked with improving the RAG quality by addressing its inflammatory outputs.

Which action would be most effective in mitigating the problem of offensive text outputs?

Options:

A.

Increase the frequency of upstream data updates

B.

Inform the user of the expected RAG behavior

C.

Restrict access to the data sources to a limited number of users

D.

Curate upstream data properly that includes manual review before it is fed into the RAG system

Question 14

A Generative AI Engineer is developing a patient-facing healthcare-focused chatbot. If the patient’s question is not a medical emergency, the chatbot should solicit more information from the patient to pass to the doctor’s office and suggest a few relevant pre-approved medical articles for reading. If the patient’s question is urgent, direct the patient to calling their local emergency services.

Given the following user input:

“I have been experiencing severe headaches and dizziness for the past two days.”

Which response is most appropriate for the chatbot to generate?

Options:

A.

Here are a few relevant articles for your browsing. Let me know if you have questions after reading them.

B.

Please call your local emergency services.

C.

Headaches can be tough. Hope you feel better soon!

D.

Please provide your age, recent activities, and any other symptoms you have noticed along with your headaches and dizziness.

Question 15

A Generative Al Engineer is setting up a Databricks Vector Search that will lookup news articles by topic within 10 days of the date specified An example query might be " Tell me about monster truck news around January 5th 1992 " . They want to do this with the least amount of effort.

How can they set up their Vector Search index to support this use case?

Options:

A.

Split articles by 10 day blocks and return the block closest to the query.

B.

Include metadata columns for article date and topic to support metadata filtering.

C.

pass the query directly to the vector search index and return the best articles.

D.

Create separate indexes by topic and add a classifier model to appropriately pick the best index.

Question 16

A Generative AI Engineer is deploying an agent using Mosaic AI Model Serving. The agent needs to access various Databricks resources, including Vector Search, Databricks SQL, and Functions. They need to find the easiest and best-practice way to authenticate the deployed agent to access these resources.

What approach should they choose?

Options:

A.

Embed authentication credentials within the agent’s code to access the required resources.

B.

Log the authentication token while logging the agent; this token will be automatically used for authentication.

C.

Set appropriate permissions on the Model Serving endpoint for the agent, as these permissions will be used when connecting to other resources.

D.

Define resource dependencies while logging the agent and deploy it with the Agent Framework.

Question 17

A Generative Al Engineer is helping a cinema extend its website ' s chat bot to be able to respond to questions about specific showtimes for movies currently playing at their local theater. They already have the location of the user provided by location services to their agent, and a Delta table which is continually updated with the latest showtime information by location. They want to implement this new capability In their RAG application.

Which option will do this with the least effort and in the most performant way?

Options:

A.

Create a Feature Serving Endpoint from a FeatureSpec that references an online store synced from the Delta table. Query the Feature Serving Endpoint as part of the agent logic / tool implementation.

B.

Query the Delta table directly via a SQL query constructed from the user ' s input using a text-to-SQL LLM in the agent logic / tool

C.

implementation. Write the Delta table contents to a text column.then embed those texts using an embedding model and store these in the vector index Look

up the information based on the embedding as part of the agent logic / tool implementation.

D.

Set up a task in Databricks Workflows to write the information in the Delta table periodically to an external database such as MySQL and query the information from there as part of the agent logic / tool implementation.

Question 18

Which of the following statements accurately identifies differences between the evaluation phase and the monitoring phase in the Generative AI application lifecycle within Databricks?

Options:

A.

The evaluation phase uses Mosaic AI Agent Evaluation and an evaluation dataset to assess an agent’s performance metrics and traces, while the monitoring phase relies on inference tables as source data for creating a metrics profile.

B.

The evaluation phase logs and traces live API calls in production, while the monitoring phase runs metrics on inference tables containing those traces.

C.

The evaluation phase ensures the agent’s responses comply with business rules in production, whereas the monitoring phase is focused on SLA and performance metrics.

D.

The evaluation phase uses all inference history to assess agent performance and readiness for production, while the monitoring phase uses only new inference-table records to monitor performance.

Question 19

A Generative AI Engineer is creating an LLM-powered application that will need access to up-to-date news articles and stock prices.

The design requires the use of stock prices which are stored in Delta tables and finding the latest relevant news articles by searching the internet.

How should the Generative AI Engineer architect their LLM system?

Options:

A.

Use an LLM to summarize the latest news articles and lookup stock tickers from the summaries to find stock prices.

B.

Query the Delta table for volatile stock prices and use an LLM to generate a search query to investigate potential causes of the stock volatility.

C.

Download and store news articles and stock price information in a vector store. Use a RAG architecture to retrieve and generate at runtime.

D.

Create an agent with tools for SQL querying of Delta tables and web searching, provide retrieved values to an LLM for generation of response.

Question 20

Which indicator should be considered to evaluate the safety of the LLM outputs when qualitatively assessing LLM responses for a translation use case?

Options:

A.

The ability to generate responses in code

B.

The similarity to the previous language

C.

The latency of the response and the length of text generated

D.

The accuracy and relevance of the responses

Question 21

A Generative Al Engineer is deciding between using LSH (Locality Sensitive Hashing) and HNSW (Hierarchical Navigable Small World) for indexing their vector database Their top priority is semantic accuracy

Which approach should the Generative Al Engineer use to evaluate these two techniques?

Options:

A.

Compare the cosine similarities of the embeddings of returned results against those of a representative sample of test inputs

B.

Compare the Bilingual Evaluation Understudy (BLEU) scores of returned results for a representative sample of test inputs

C.

Compare the Recall-Onented-Understudy for Gistmg Evaluation (ROUGE) scores of returned results for a representative sample of test inputs

D.

Compare the Levenshtein distances of returned results against a representative sample of test inputs

Question 22

A Generative AI Engineer is building a Databricks-hosted assistant that must (1) query Unity Catalog tables with row and column permissions enforced, and (2) avoid managing any external infrastructure. The team wants the LLM to use governed data access through tools exposed via MCP.

Which MCP server choice meets these constraints?

Options:

A.

Use a managed Databricks MCP server integrated with Unity Catalog.

B.

Use an external community MCP server for SQL and pass Unity Catalog tokens in prompts.

C.

Run a custom MCP server on a self-managed VM that proxies the Unity Catalog API.

D.

Expose JDBC directly to the model and enforce permissions in application code.

Question 23

A Generative AI Engineer wants to build an LLM-based solution to help a restaurant improve its online customer experience with bookings by automatically handling common customer inquiries. The goal of the solution is to minimize escalations to human intervention and phone calls while maintaining a personalized interaction. To design the solution, the Generative AI Engineer needs to define the input data to the LLM and the task it should perform.

Which input/output pair will support their goal?

Options:

A.

Input: Online chat logs; Output: Group the chat logs by users, followed by summarizing each user’s interactions

B.

Input: Online chat logs; Output: Buttons that represent choices for booking details

C.

Input: Customer reviews; Output: Classify review sentiment

D.

Input: Online chat logs; Output: Cancellation options

Question 24

A Generative Al Engineer is using an LLM to classify species of edible mushrooms based on text descriptions of certain features. The model is returning accurate responses in testing and the Generative Al Engineer is confident they have the correct list of possible labels, but the output frequently contains additional reasoning in the answer when the Generative Al Engineer only wants to return the label with no additional text.

Which action should they take to elicit the desired behavior from this LLM?

Options:

A.

Use few snot prompting to instruct the model on expected output format

B.

Use zero shot prompting to instruct the model on expected output format

C.

Use zero shot chain-of-thought prompting to prevent a verbose output format

D.

Use a system prompt to instruct the model to be succinct in its answer

Question 25

A Generative Al Engineer has successfully ingested unstructured documents and chunked them by document sections. They would like to store the chunks in a Vector Search index. The current format of the dataframe has two columns: (i) original document file name (ii) an array of text chunks for each document.

What is the most performant way to store this dataframe?

Options:

A.

Split the data into train and test set, create a unique identifier for each document, then save to a Delta table

B.

Flatten the dataframe to one chunk per row, create a unique identifier for each row, and save to a Delta table

C.

First create a unique identifier for each document, then save to a Delta table

D.

Store each chunk as an independent JSON file in Unity Catalog Volume. For each JSON file, the key is the document section name and the value is the array of text chunks for that section

Question 26

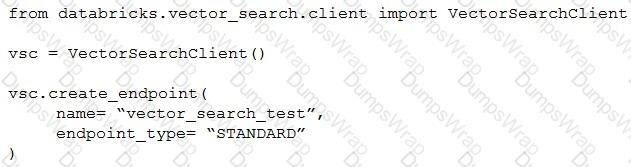
A Generative AI Engineer I using the code below to test setting up a vector store:
as

Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?

Options:

A.

vsc.get_index()

B.

vsc.create_delta_sync_index()

C.

vsc.create_direct_access_index()

D.

vsc.similarity_search()

Question 27

A Generative AI Engineer is implementing a supervisor agent and two specialist agents in Databricks: a Sales Analyst for revenue questions and an HR Analyst for staff questions. Each specialist must retrieve data only from its own governed domain, and the engineer wants to preserve that separation using Databricks-native data access for each agent rather than building custom retrieval logic.

What should the engineer implement?

Options:

A.

Create separate Knowledge Assistants for Sales and HR and have each specialist retrieve from the corresponding assistant.

B.

Create two separate Genie Spaces for Sales and HR, each scoped to its own governed datasets, and have each specialist agent call the appropriate Space through the API.

C.

Create a shared Genie Space over both domains, but use distinct service principals and Unity Catalog grants for each specialist agent’s API access.

D.

Create a single Genie Space over both domains and rely on the supervisor agent to route only sales questions to the Sales Analyst and HR questions to the HR Analyst.

Page: 1 / 9
Total 90 questions